
Noindex vs Robots Blocking: Plan a Clean Search Removal
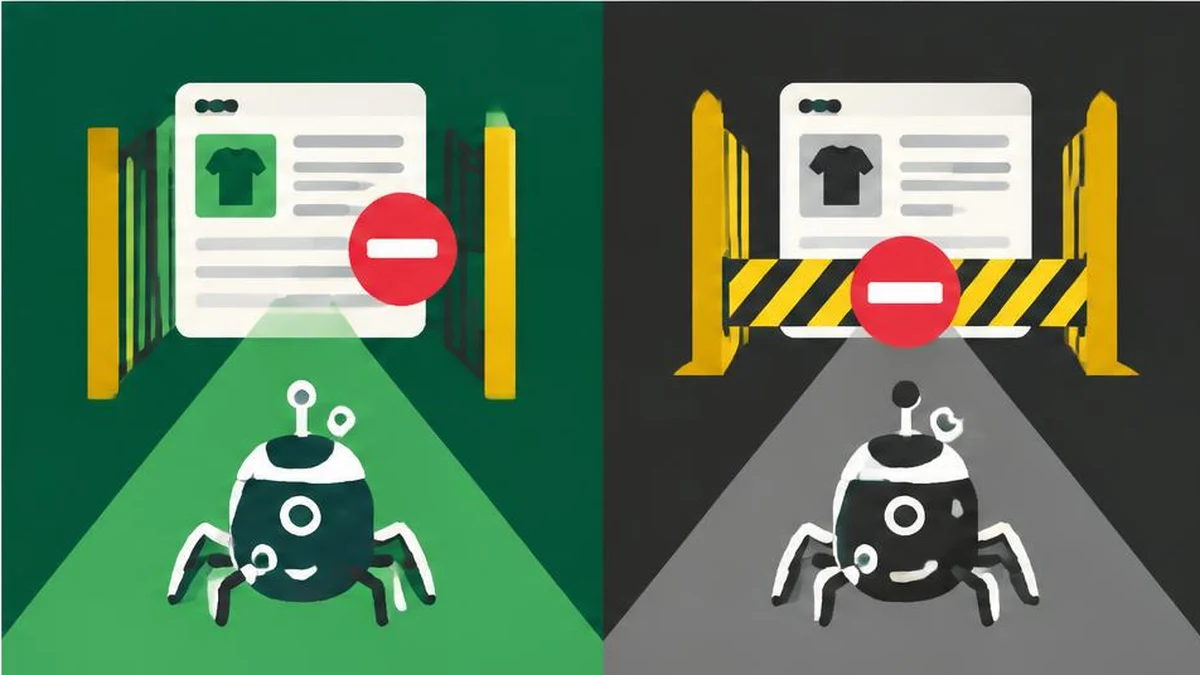
Use an indexing-control checklist to distinguish search removal from crawl management and private access, then verify the deployed instructions rather than the template alone.
Define what you want to stop
“Hide this page” is not a complete technical requirement. You might want to prevent its contents appearing in Google, stop repeated crawling of low-value URLs, or prevent unauthorized people reading it. These goals need different controls. Applying them interchangeably can leave a known URL visible or expose information you intended to protect.
Google’s robots meta and header documentation describes page-level indexing and serving rules. A noindex instruction addresses search inclusion. A robots.txt disallow rule addresses crawling. Neither is an access-control system. For genuinely private material, arrange appropriate authentication and authorization rather than relying on search settings.
Let the crawler read the removal instruction
The central dependency is simple: Google must be able to access a resource to read its noindex instruction. If robots.txt blocks that access, the instruction inside the response may never be seen. Adding both controls at once is not necessarily stronger protection; it can prevent the removal mechanism from working as intended.
For an accessible page you want removed from search, first identify any crawl block, then arrange a crawlable response containing the intended noindex instruction. Keep the page available to the crawler while Google processes that instruction. Do not promise a fixed removal deadline or tell stakeholders that saving a template instantly updates search results.
Document the exact URLs involved. Similar paths, query parameters and alternate hostnames can receive different responses. A successful check on one example does not prove the entire group has been handled correctly.
Choose a response-level implementation
For HTML, a robots meta tag belongs in the page head. For example, a robots meta element with content set to noindex expresses the exclusion instruction. An X-Robots-Tag HTTP response header can also carry indexing rules and is useful for non-HTML resources such as PDFs.
Check where the instruction is actually set. A content-management plugin may add a tag, while a server or delivery layer adds a header. Looking at only one layer can miss an old restrictive setting. Google’s documentation explains that conflicting applicable rules are combined restrictively; adding an index instruction elsewhere is not a dependable way to cancel an existing noindex.
The meta tag analyzer can support an HTML metadata check. Do not assume it proves the response headers or Google’s rendered interpretation. Inspect headers with an appropriate HTTP tool, and use suitable browser or Search Console inspection when rendering is relevant.
Keep crawl-management work separate
There are legitimate reasons to limit crawling of repetitive URL spaces. Google’s faceted-navigation guidance discusses the cost of unnecessary filter combinations and approaches to preventing their crawling. That is a different job from ensuring Google reads noindex on an already known page.
Write two policies if necessary: one for removing existing URLs from search, and another for avoiding future crawl waste. The robots.txt generator can help draft rules after that policy is clear. Review each pattern against examples that should be blocked and examples that must remain accessible. A generated rule still needs deployment testing.
Verify a small representative test set
Prepare a worksheet with the URL, current status, crawl permission, HTML robots tag, X-Robots-Tag header and intended outcome. Include a page being removed, a page staying indexable, an alternate parameter version and a non-HTML file if relevant. Record observations rather than assuming templates behave identically.
Use text compare to review proposed and deployed directive lists. It can reveal an unexpected rule or missing entry, but cannot tell whether Google has recrawled a resource. Recheck the actual live response after caches and deployment layers have updated, then monitor the search-side evidence separately.
Plan restoration before it is needed
Temporary exclusions deserve an owner and a reversal checklist. To make a page eligible again, remove the applicable noindex instructions, allow crawling and verify the resulting response. Also confirm that an older header or template override is not still applying the restriction.
Restoring technical eligibility is not a promise of immediate indexing. Likewise, removing a result from search does not erase copies already saved elsewhere or stop visitors who know the address. Keep privacy, crawler access and indexing eligibility as separate acceptance criteria so that a search-cleanup task does not get mistaken for a security fix.
Frequently asked questions
Does robots.txt guarantee removal from search?
No. It controls crawling and can prevent Google from seeing a page-level removal instruction.
Why must noindex remain crawlable?
Google needs access to the response to discover and process the instruction.
Can I use noindex for PDFs?
Use an appropriate X-Robots-Tag HTTP response header for non-HTML resources such as PDFs.
Does an index tag override noindex elsewhere?
Do not rely on it. Google combines applicable conflicting rules restrictively; remove the unintended restriction.
Is noindex appropriate protection for private files?
No. Search exclusion is not access control; private resources need appropriate authentication and authorization.
How quickly will removal happen?
There is no fixed deadline in this checklist. Google must access and process the updated response.
Useful on MayreDukaan
Sources
Facts last checked against these sources on 17 Nov 2026, 06:44 Pakistan time.
Images: Original AI-generated illustration by MayreDukaan; conceptual, not a product screenshot.
More trending articles
 Shopping and DealsUK Fake Online Shops: Check the Seller Before Paying17 Nov 2026 · 5 min read
 AI and SoftwareVerify an AI Summary Against the Original Document17 Nov 2026 · 5 min read
 Artificial IntelligenceGemini Activity Privacy: History, Training and Deletion17 Nov 2026 · 5 min read
 AI and SoftwarePrepare a Spreadsheet for Safer Gemini Analysis17 Nov 2026 · 4 min read