
Urdu and English OCR: Turn Scans into Editable Text
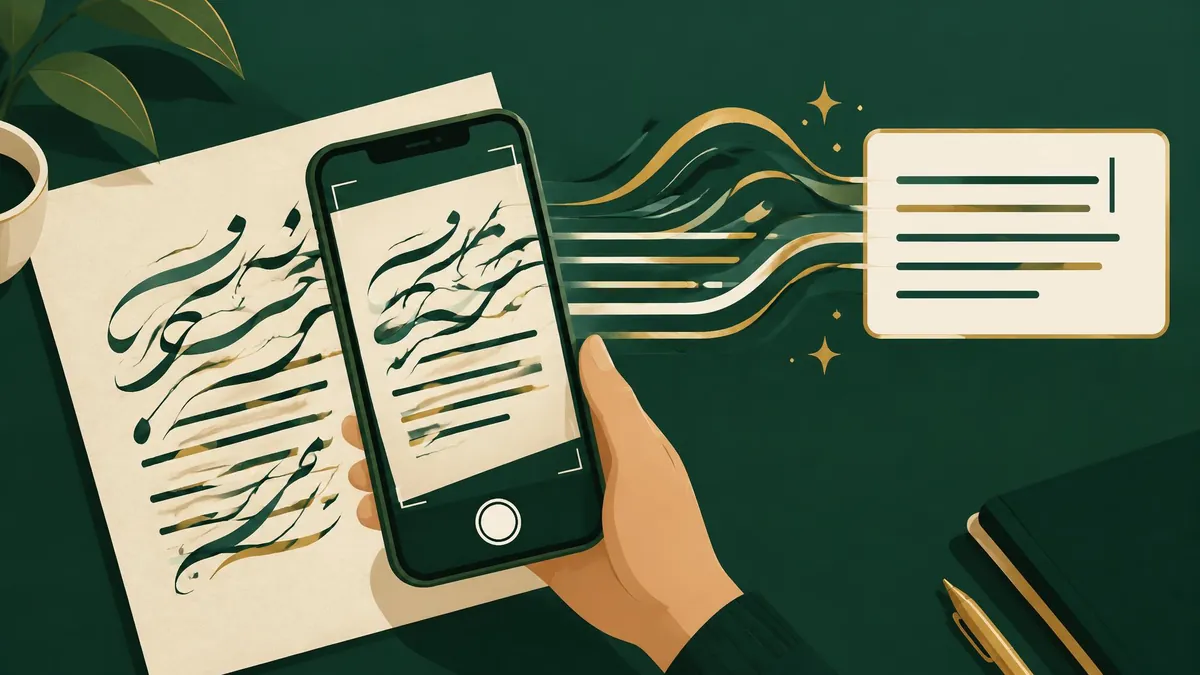
For Urdu and English OCR, Google Drive provides an officially documented method: upload a supported image or PDF on a computer, then open it with Google Docs. Google’s supported-language list includes Urdu and both American and British English; that is language support, not a promise of perfect transcription.
For Urdu and English OCR, Google Drive provides an officially documented method: upload a supported image or PDF on a computer, then open it with Google Docs. Google’s supported-language list includes Urdu and both American and British English; that is language support, not a promise of perfect transcription.
Use a tool with confirmed Urdu support
Do not infer Urdu recognition from a product's support for Arabic, right-to-left interfaces, or document scanning. Those are different capabilities. Google Drive Help explicitly lists Urdu alongside English in its OCR-supported languages, and says Drive detects the document's language. (Google Drive Help)
This guide therefore uses Google Drive and Docs rather than promising that every scanning application can extract Urdu. The documented input formats include multipage PDFs and JPEG, PNG, and GIF photo files. Choose a small representative sample first when the document contains unusual typography or a mixture of scripts.
OCR stands for optical character recognition. It turns pictures of characters into text you can edit or search. It does not establish whether the document's statements are true, whether a name is spelled correctly, or whether an amount is financially valid.
Prepare the scan before uploading
Google's recommendations are specific:
- Keep the file 2 MB or smaller for this workflow.
- Make text at least 10 pixels high.
- Ensure the page is right-side up.
- Use sharp images with even lighting and clear contrast.
- Prefer common fonts where you control the source. (Google Drive Help)
For a photograph, capture the page squarely and keep the whole text area in focus. Avoid cutting off diacritics or the tops and bottoms of lines. If the page is glossy, adjust the light rather than accepting glare over important words.
Do not aggressively reduce an image until the lettering becomes soft merely to meet a size target. A smaller file that obscures character shapes defeats the purpose. For a long PDF, processing relevant sections separately may be more sensible than degrading every page.
Run OCR through Google Docs
- Sign in to Google Drive on a computer.
- Upload the prepared image or PDF if it is not already in Drive.
- Right-click the file.
- Select Open with > Google Docs.
- Review the recognized text in the resulting document.
- Keep the source scan available while correcting the transcription. (Google Drive Help)
Google's explanation of its Drive OCR describes the document opening with the original image followed by extracted text. That arrangement helps with comparison, but you should still inspect the entire output rather than assuming the first readable paragraph proves the rest is accurate. (Google Research)
Choose a test page containing the hardest material: small Urdu text, an English reference number, and any punctuation or table entries that matter. Assess that result before sending a large batch through the same process.
Proofread Urdu and mixed-script text
Compare the output line by line with the source. Give particular attention to names, letter shapes that differ by dots, omitted punctuation, and words whose spacing has changed. For mixed English and Urdu, inspect the reading order of phrases as well as individual characters.
Numbers need their own pass. Phone numbers, dates, identity references, and money amounts can look plausible even after one character is wrong. Check them against the scan independently of the surrounding sentence.
When moving recognized text to another application, verify paragraph direction and the order of brackets, slashes, and embedded English terms. A display problem after pasting is not necessarily the same as a recognition problem. Keep the original scan as the reference until both text and presentation are checked.
Do not expect tables or columns to survive intact
Google warns that formatting may not transfer completely. Bold, italics, font properties, and line breaks are more likely to be retained, while lists, tables, columns, footnotes, and endnotes are unlikely to be detected reliably. (Google Drive Help)
For a bilingual table, rebuild the structure after checking the text. Confirm which value belongs to each row and heading. Do not paste a visually jumbled OCR block into a spreadsheet and assume it has preserved the relationships from the page.
For handwriting or ornate printed styles, test a sample rather than promising an accuracy level. Google's language list does not provide a blanket guarantee for every writer, font, or scan condition.
Why Microsoft Lens is not the recommended route
As of November 16, 2026, Microsoft Lens is not a suitable new-scanning recommendation. Microsoft's retirement notice says support ended after February 9, 2026, and new scans stopped after March 9, 2026. Microsoft recommends OneDrive scanning as an alternative, but that recommendation is not verification of Urdu OCR support. (Microsoft Support)
A scan is simply a captured document until recognition has produced usable text. Do not present OneDrive's scanning feature as a confirmed substitute for this Urdu OCR workflow without a separate official language-support source.
Use related PDF tools only for preparation
The PDF splitter can create smaller PDF sections for review. The splitting guide helps identify the right page positions. Neither performs OCR.
If starting with separate photos, the JPG-to-PDF guide explains a document-assembly task, not text recognition. MayreDukaan has no OCR tool. For confidential material, get approval before uploading to Drive and follow your organization's storage and retention requirements.
Frequently asked questions
Does Google Drive OCR officially support Urdu?
Yes. Google Drive Help lists Urdu, American English, and British English among its supported OCR languages. Output still needs proofreading.
Can I use Microsoft Lens for new scans now?
Microsoft says new scans stopped after March 9, 2026. As of November 16, 2026, it should not be recommended as a current scanning workflow.
Will OCR preserve a bilingual table?
Do not count on it. Google warns that tables and columns may not be detected reliably. Verify the text and rebuild the structure when necessary.
Frequently asked questions
Does Google Drive OCR officially support Urdu?
Yes. Google Drive Help lists Urdu, American English, and British English among its supported OCR languages. Output still needs proofreading.
Can I use Microsoft Lens for new scans now?
Microsoft says new scans stopped after March 9, 2026. As of November 16, 2026, it should not be recommended as a current scanning workflow.
Will OCR preserve a bilingual table?
Do not count on it. Google warns that tables and columns may not be detected reliably. Verify the text and rebuild the structure when necessary.
Useful on MayreDukaan
Sources
- Google Drive Help: Convert PDF and photo files to text
- Google Research: Paper to Digital in 200+ languages
- Microsoft Support: Retirement of Microsoft Lens
Facts last checked against these sources on 16 Nov 2026, 07:00 Pakistan time.
Images: Illustration created for MayreDukaan (not a photo)
More trending articles
 PDF and Document ToolsPowerPoint to PDF: Export Slides or Handouts Safely16 Nov 2026 · 5 min read
 PDF and Document ToolsWord to PDF: Export Documents Ready for Sharing16 Nov 2026 · 5 min read
 PDF and Document ToolsExcel to PDF: Keep Columns and Pages Readable16 Nov 2026 · 5 min read
 PDF and Document ToolsPDF to Excel: Import Tables and Verify the Data16 Nov 2026 · 5 min read