
SEO infographics
Crawling, indexing, sitemaps, canonicals and Core Web Vitals.
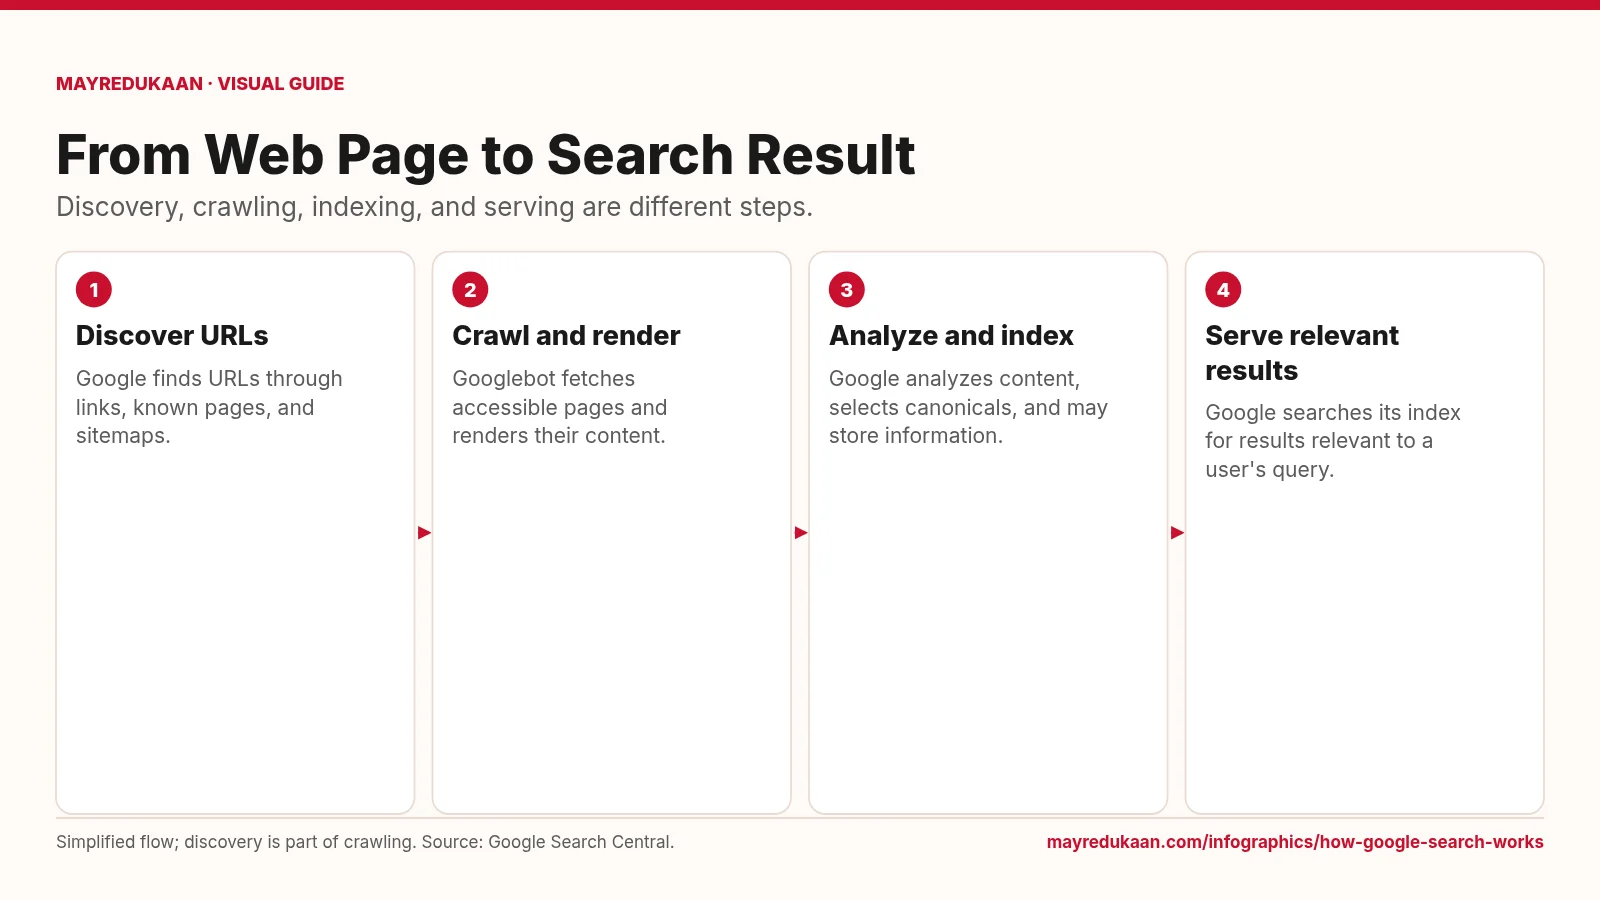
How Google Search Works
A page must be discovered and processed before its information can compete to appear for a search.
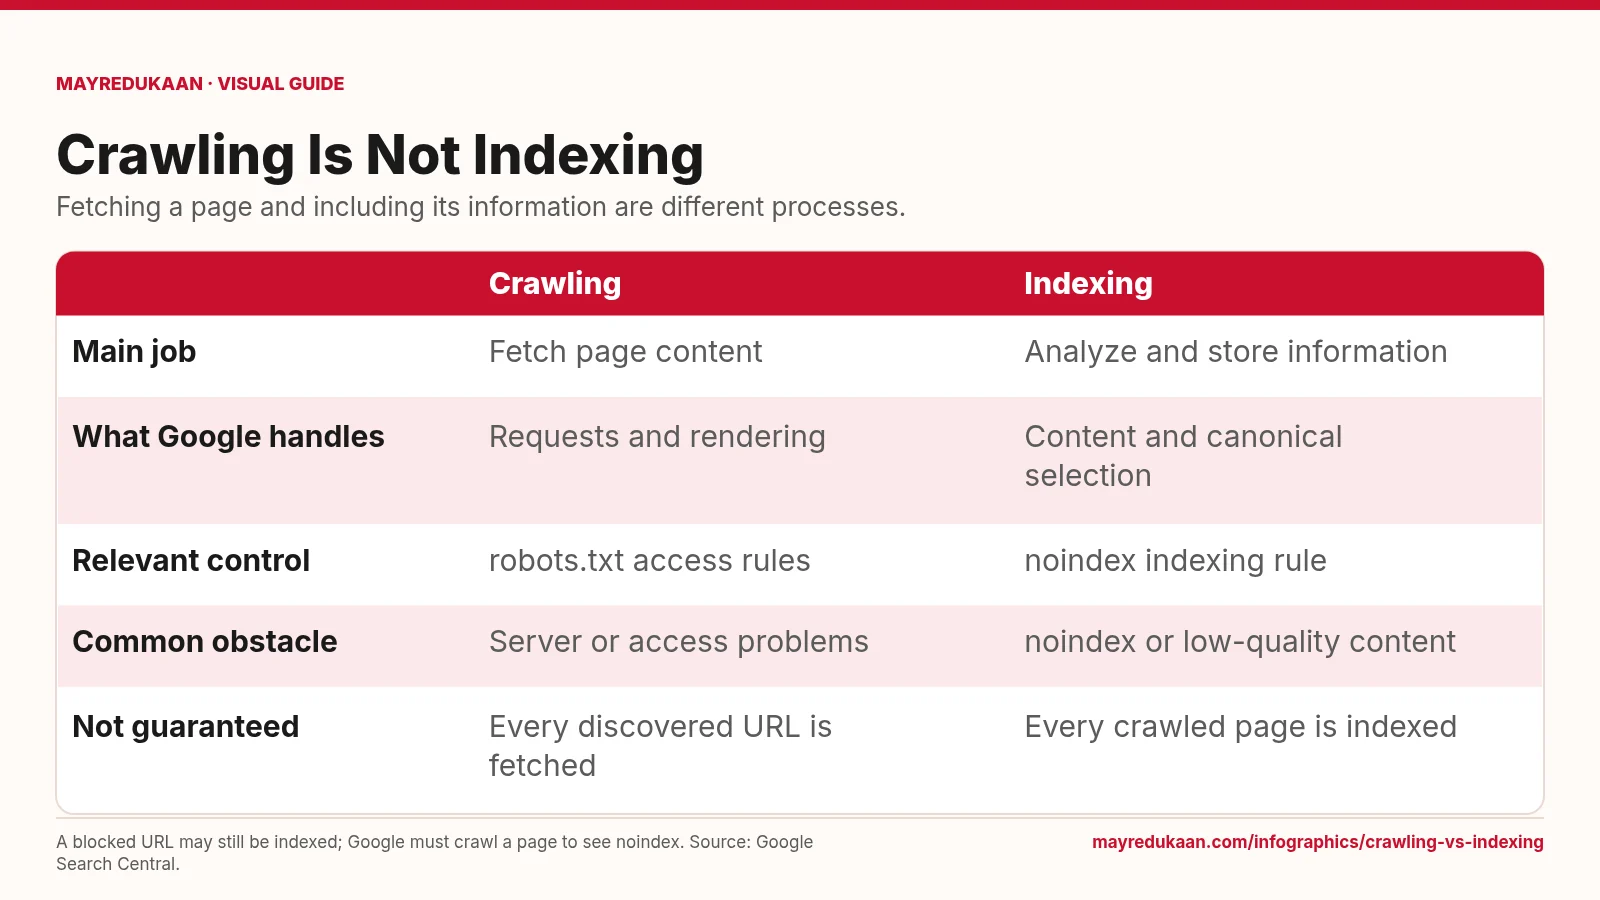
Crawling vs Indexing
Use crawl controls for fetching and indexing rules for whether content belongs in Search.
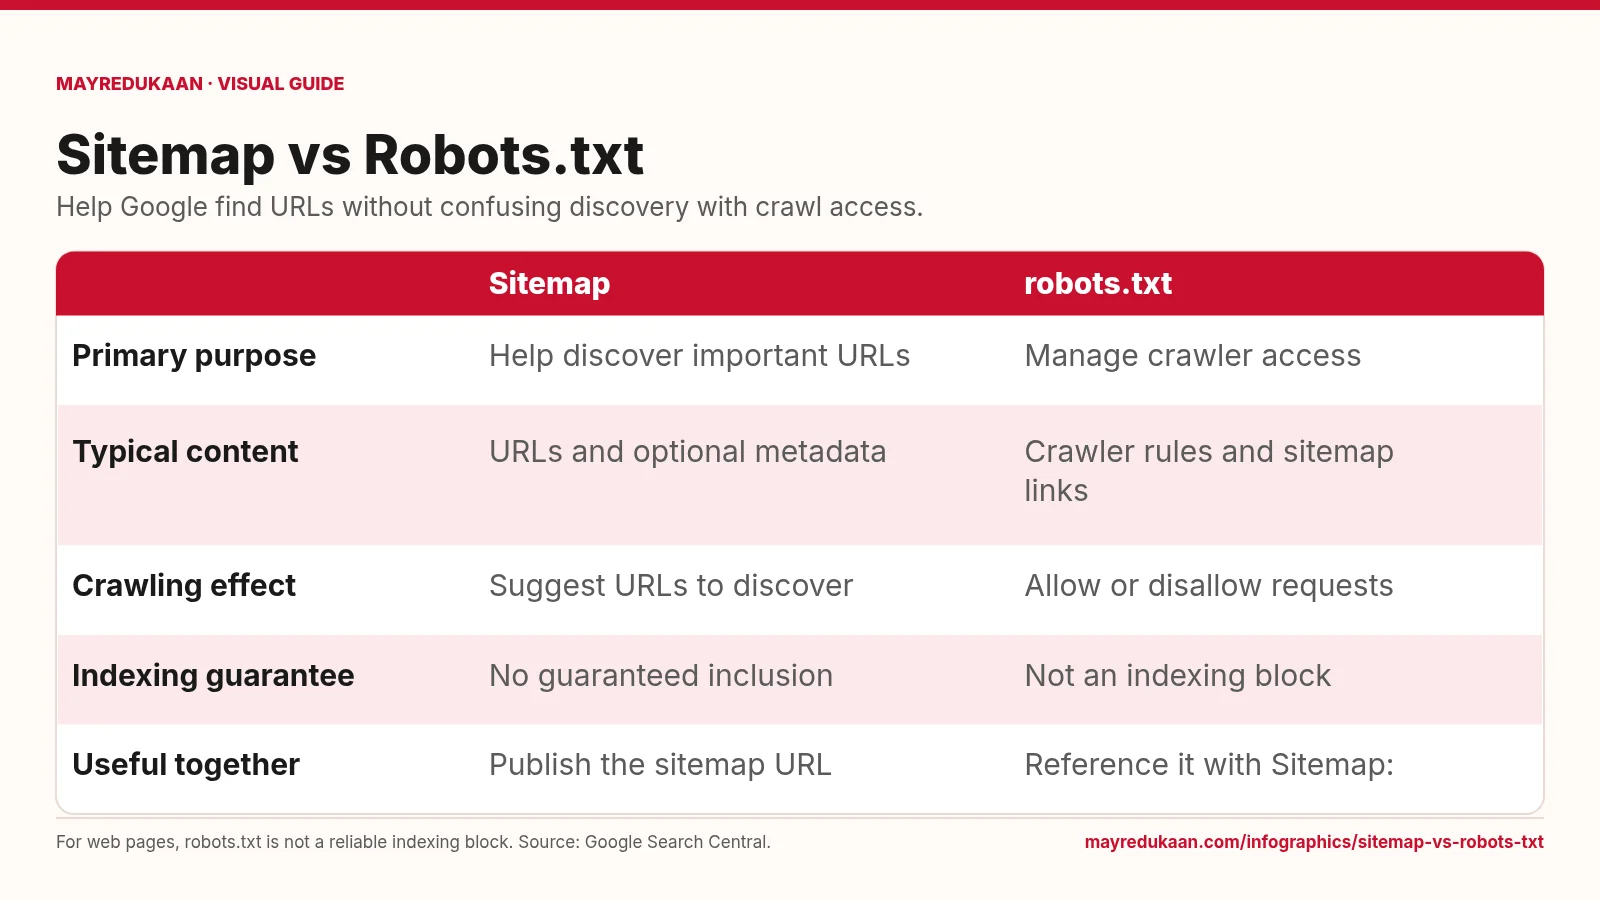
Sitemap vs Robots.txt
Sitemaps support URL discovery, while robots.txt sets crawl-access rules for compliant crawlers.
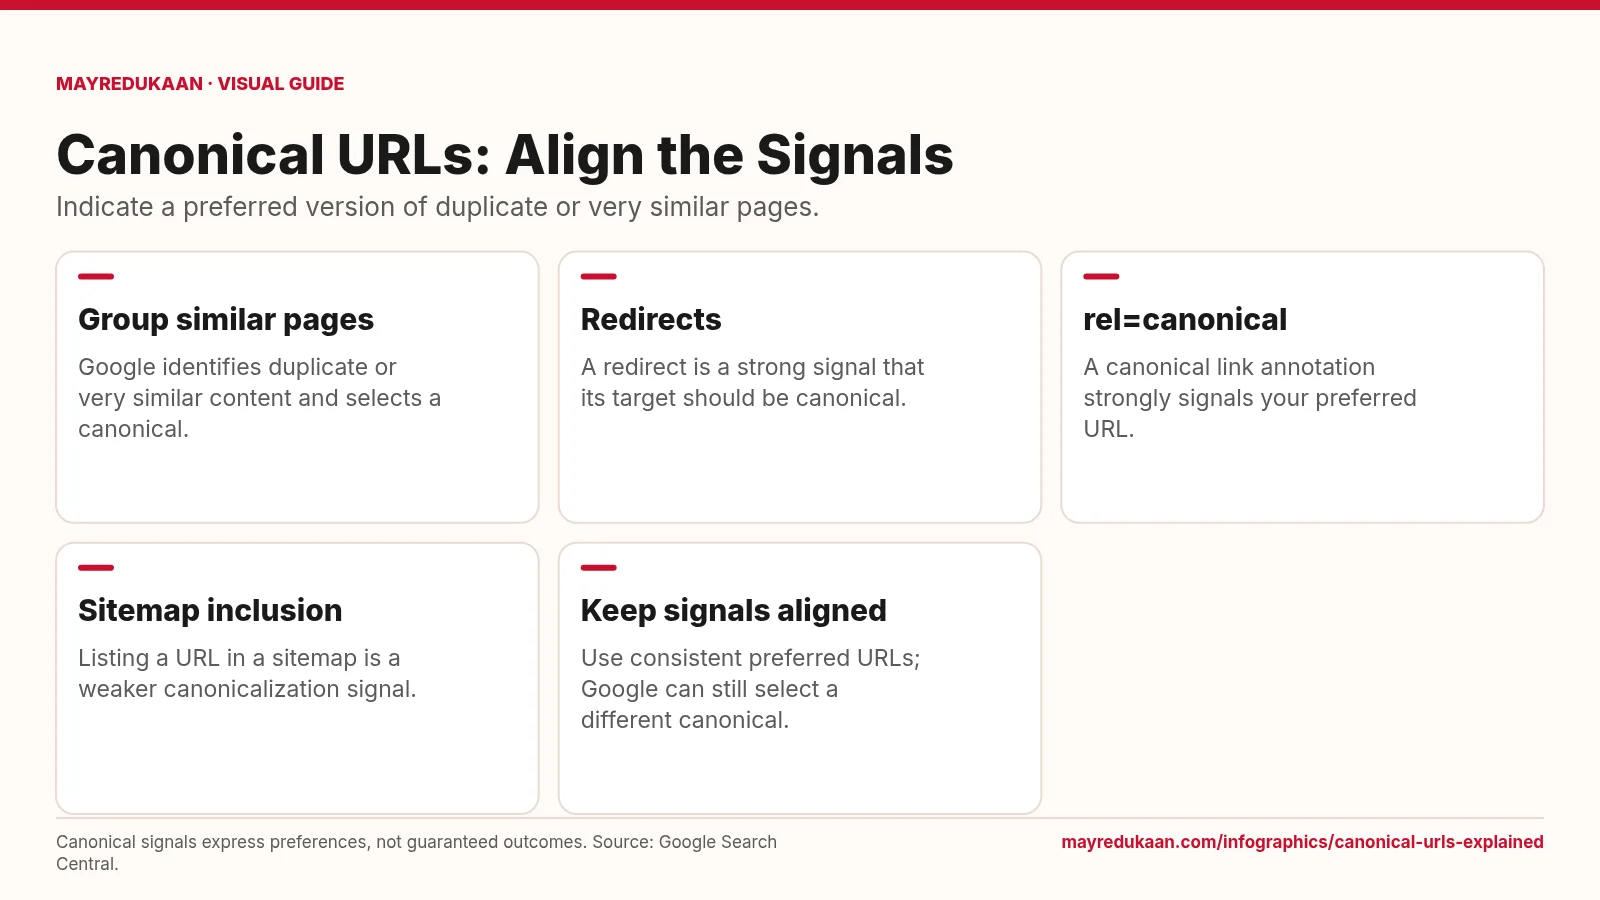
Canonical URLs Explained
Canonicalization helps Google choose a representative URL from duplicate or very similar pages.
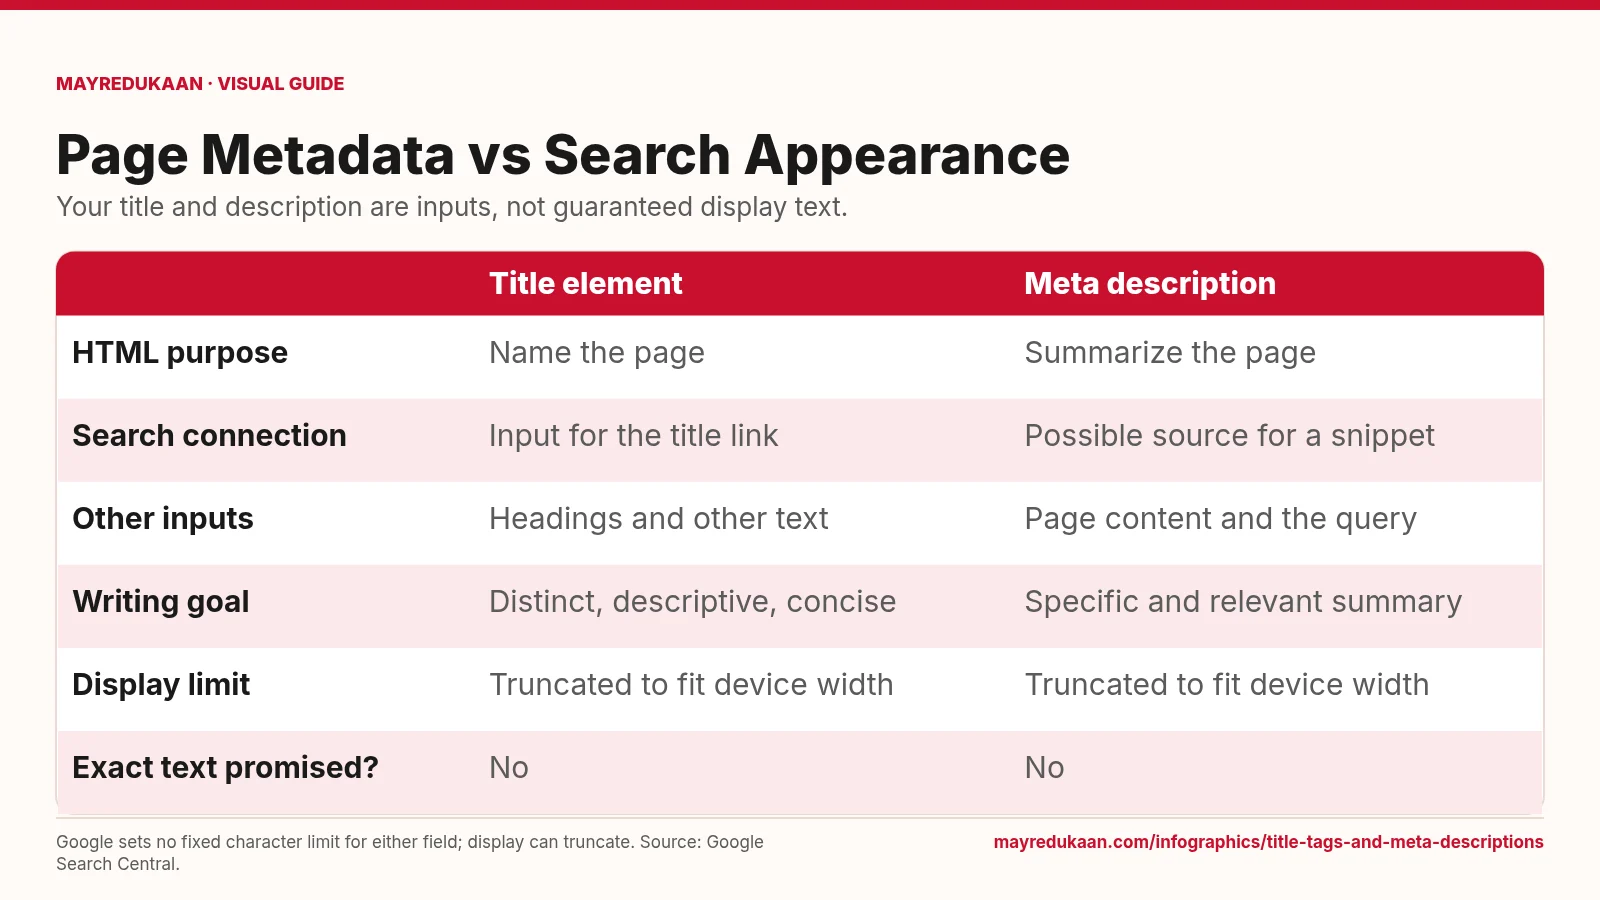
Title Tags and Meta Descriptions
Write accurate page-specific metadata while allowing for Google's automated title links and query-dependent snippets.
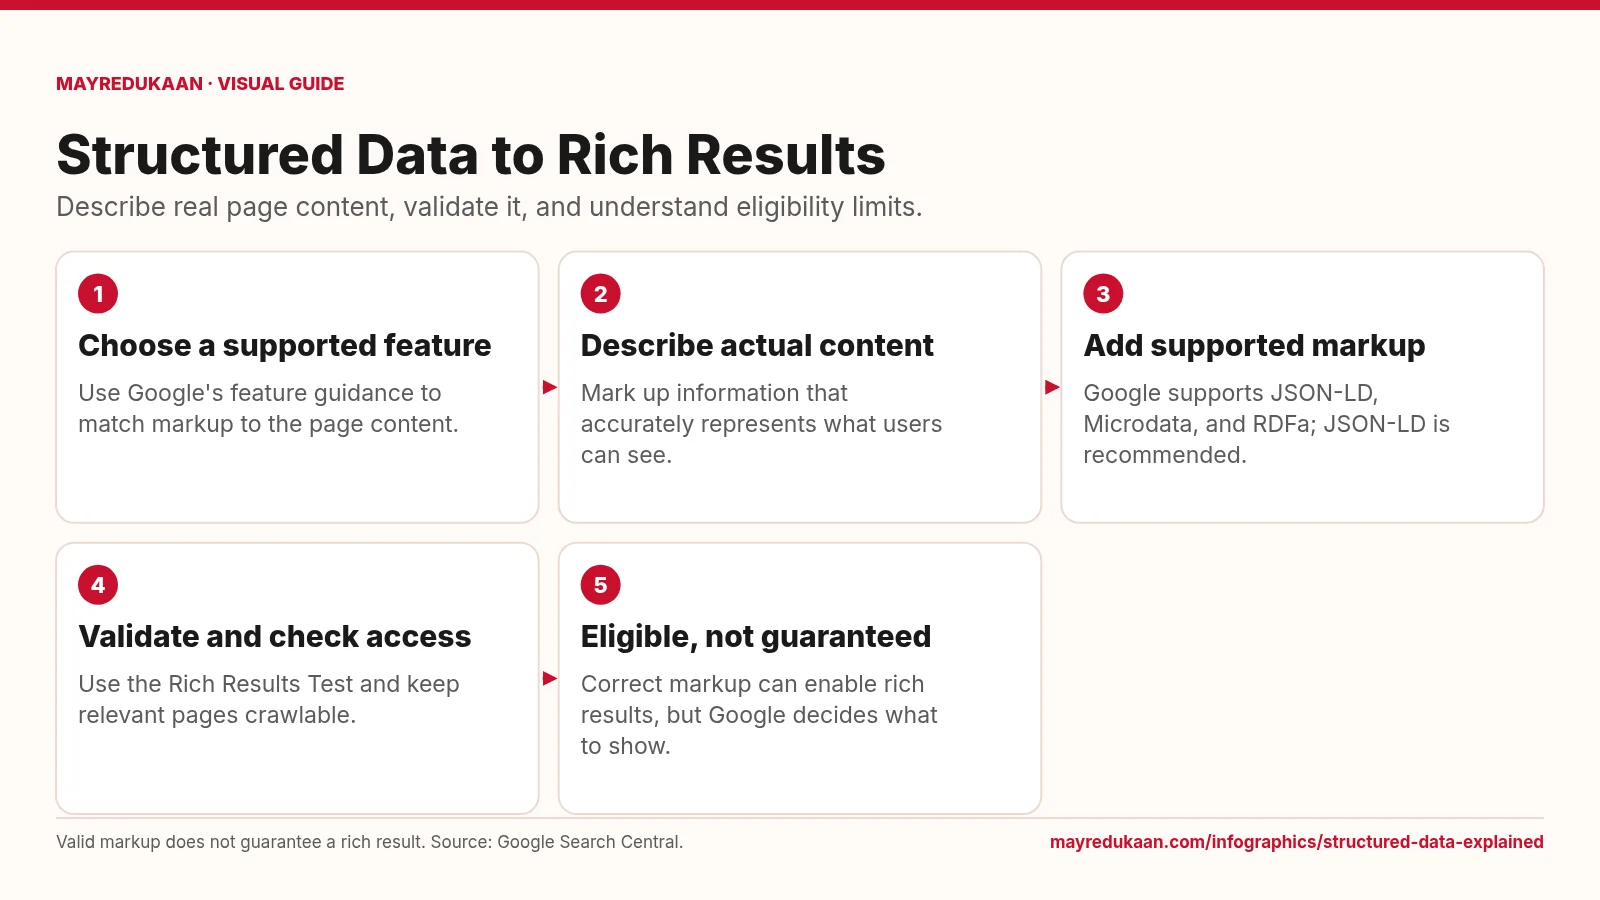
Structured Data Explained
Structured data helps Google understand content and can establish eligibility for supported rich results.
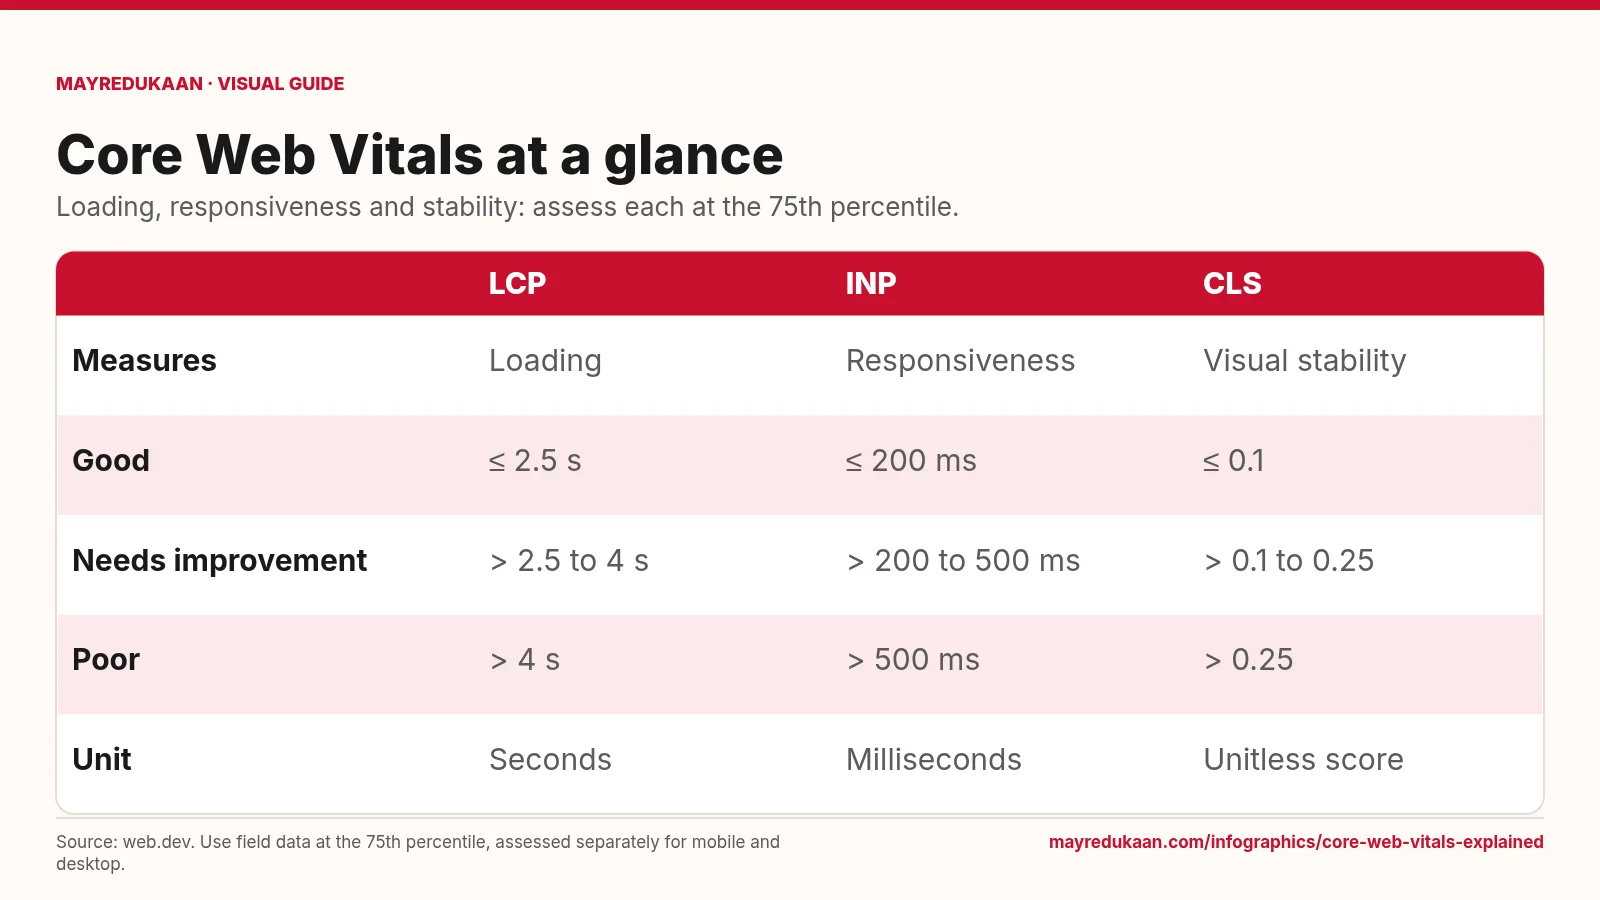
Core Web Vitals explained
Core Web Vitals evaluate three different aspects of a page's real-world user experience.
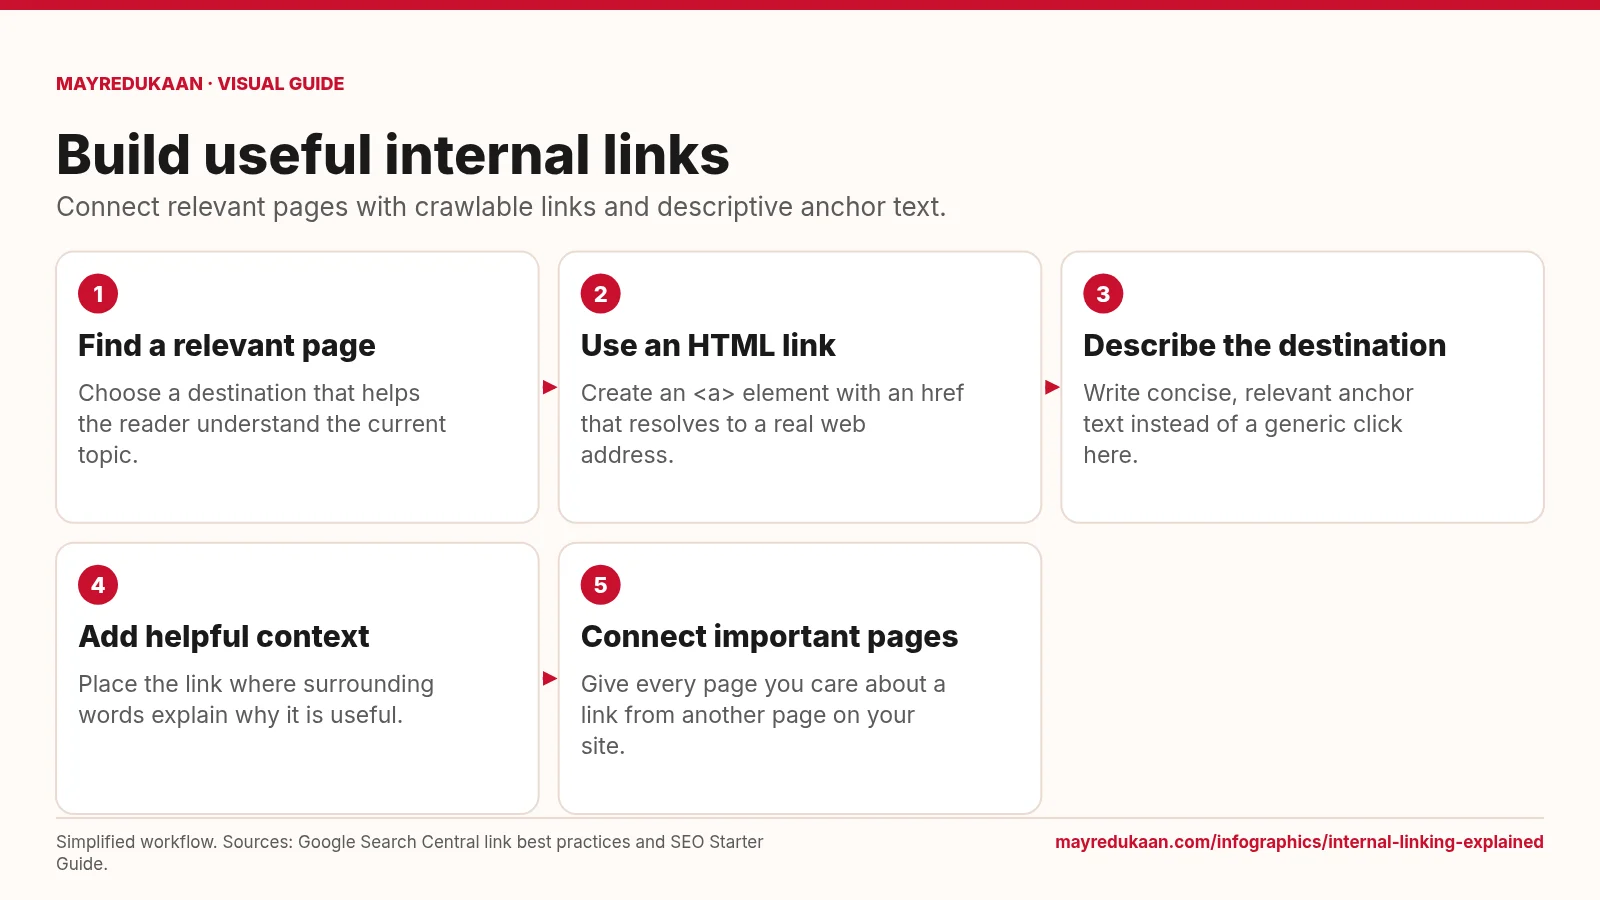
Internal linking explained
An effective internal link provides both a usable route and a clear reason to follow it.